0 photos
is all it takesFrom roughly six clear images of your face, an open-source model can re-identify you on public camera footage with about 70% confidence — no special hardware required.
Open facial-recognition research
An open lab for seeing how facial recognition actually works — and where it quietly fails.
scroll
Your face isn't a password — it's a permanent key you can never change. And the math to read it is already open source.
From roughly six clear images of your face, an open-source model can re-identify you on public camera footage with about 70% confidence — no special hardware required.
Recognition models don't keep a photo. They compress your face into a vector of 512 floating-point values — a fingerprint that fits on a single line of text.
Government testing has found many algorithms misidentify some demographic groups up to 10–100 times more often than others. The bias lives in the data.
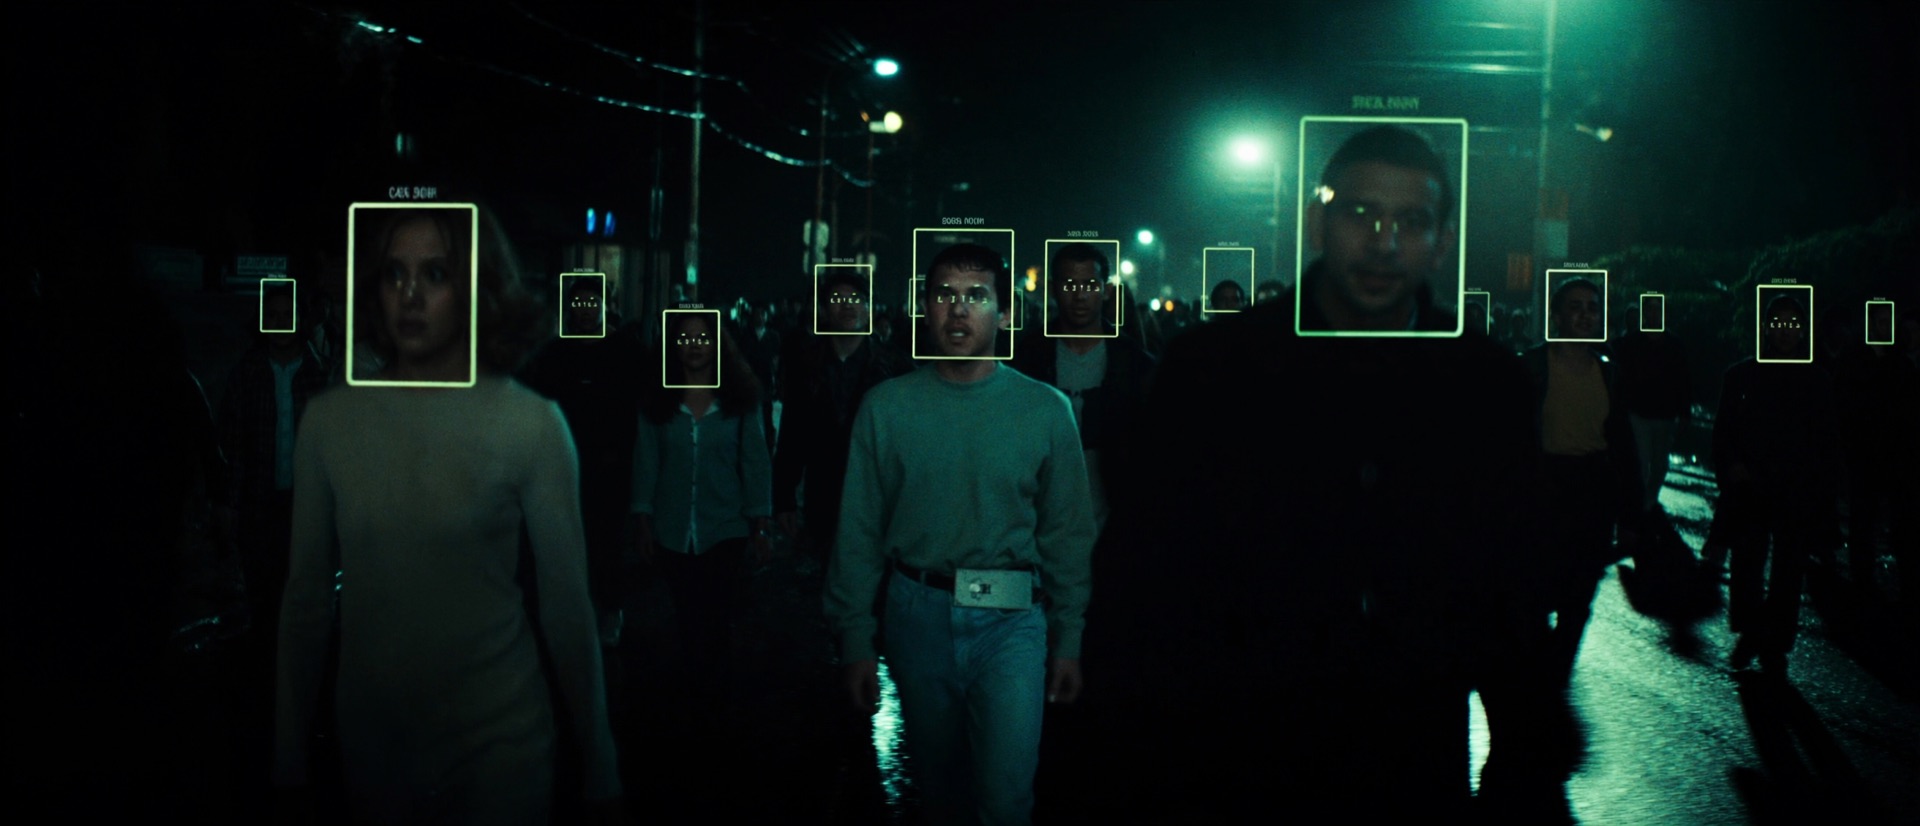
At least one company has built a searchable index of more than 30 billion facial images pulled from the open web — most people in it never agreed to be there.
Leak a password and you change it in seconds. Leak your faceprint and it's compromised for the rest of your life. You only get one face.
No tap, no badge, no opt-in. Modern systems pick a face out of a moving crowd, from across a street, the moment it appears on camera.
NanoFID is a research bench, not a product pitch. You are both the subject and the auditor.
Upload a handful of clear photos of your own face. Six is enough to begin.
The model turns those pixels into a 512-number embedding — the same primitive production FaceID systems use.
Live tests and bias metrics show where the model is confident, brittle, or quietly unfair.